publications
publications in reversed chronological order.
2026
-
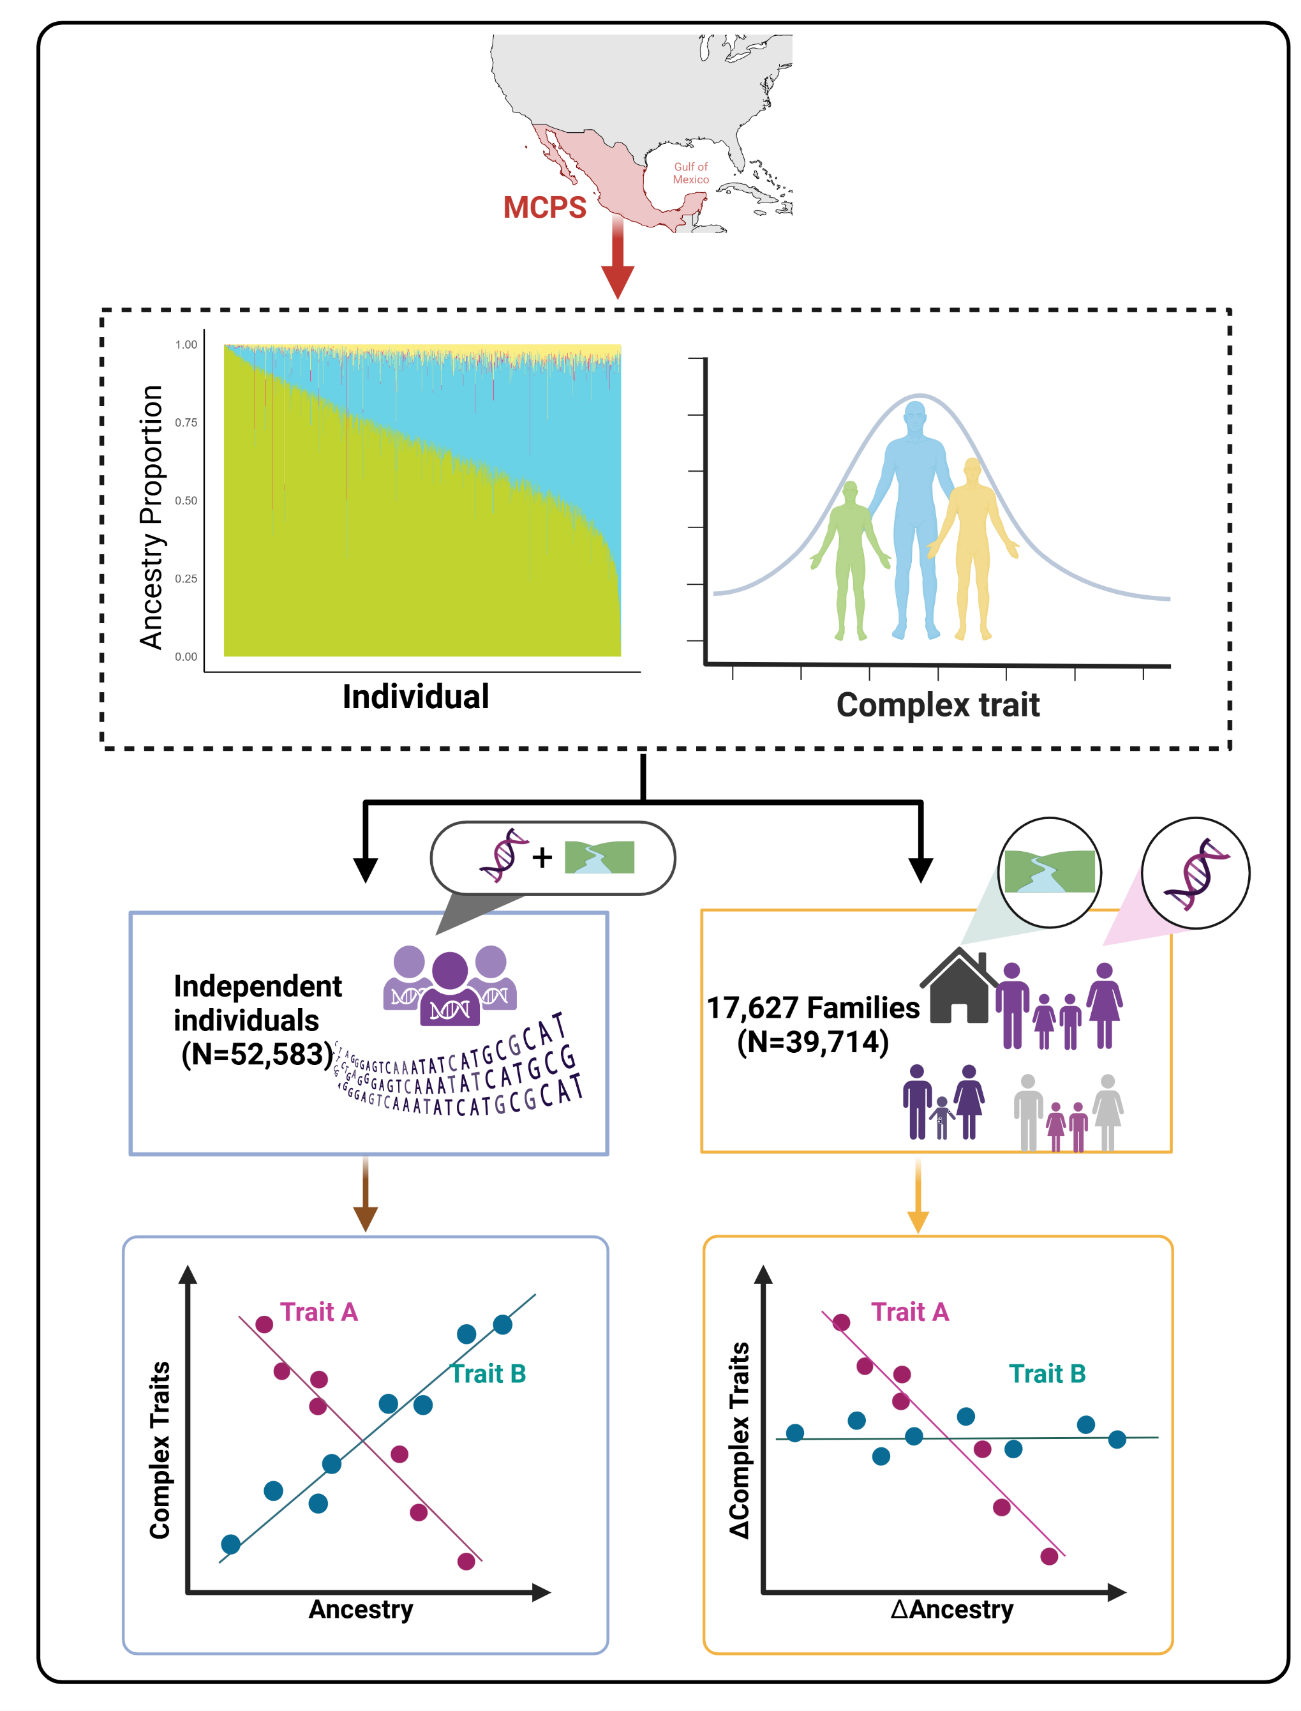 Within-family effect of ancestry on complex traits in a Mexican populationSiqi Wang, Jaime Berumen, Alejandra Vergara-Lope, and 15 more authorsNature, 2026
Human populations differ in disease prevalence and phenotypes, but the extent to which differences are caused by genetic factors is unknown for most complex traits. Comparing phenotypic means across populations is confounded by environmental differences and using polygenic predictors can lead to biased inference. Family-based analyses of people of genetically admixed ancestry enable estimation of ancestry effects unconfounded by ancestry–environment correlations. Here we leverage genetic data from admixed adults in the Mexico City Prospective Study to estimate within-family ancestry effects. We assessed genetic ancestry and 15 complex traits in 52,583 unrelated people and 39,714 relatives from 17,627 families. At the population level, relative to European ancestry, the effect of Indigenous American ancestry was −1.98 s.d. (P < 2 × 10⁻¹⁶) for height and a natural log odds ratio of 1.73 (95% confidence interval, 1.54–1.92) for type 2 diabetes. Within families, the effect of Indigenous American ancestry was −1.51 s.d. (P = 10⁻⁸) for height and natural log odds ratio of 5.13 (95% confidence interval, 2.48–7.78) for type 2 diabetes. These effects are supported by between-ancestry differences in trait-increasing allele counts and evidence of selection at trait-associated loci. We found no within-family ancestry effect on educational attainment or other traits despite significant associations at the population level, implying environmental causes or confounding. Overall, this study provides an experimental design to study between-ancestry genetic effects and identifies significant ancestry differences for height, type 2 diabetes and metabolic traits in a genetically diverse population from Mexico City.
- Genomic-Relatedness Matching Expands Population Coverage, Improves Power, and Reduces Bias in Genetic Association AnalysesDhruva Jaishankar, Tamara Gjorgjieva, Jonathan Jala, and 5 more authorsmedRxiv, 2026Preprint
We introduce a novel approach, Genomic-Relatedness-Matched Association (GRMA) studies, as an alternative to genome-wide association studies (GWAS). GWAS are typically restricted to samples of mostly unrelated individuals with a single, shared continental ancestry and nevertheless can still be biased by gene-environment correlation and assortative mating. In contrast, GRMA can be implemented in ancestrally diverse samples—retaining individuals of mixed or underrepresented ancestries and eliminating the need to assign labels to ancestry groups—and can reduce bias relative to standard GWAS. GRMA matches each individual to a group of controls whose pairwise relatedness with the individual exceeds a user-specified threshold. It generates SNP-level summary statistics based on within-group associations. In applications using the UK Biobank and All of Us data, we find that GRMA compares favorably to GWAS methods in terms of bias, precision, and population coverage. GRMA enables several novel findings; for example, we find that “genetic nurture” is unlikely to be an important source of genome-wide bias in population GWAS of body mass index, height, and educational attainment. The method is computationally efficient and supported by open-source software, facilitating its application in large-scale scientific and health-related studies.
-
 Social-Science Genomics: Progress, Challenges, and Future DirectionsDaniel J. Benjamin, David Cesarini, Patrick Turley, and 1 more authorJournal of Economic Literature, 2026Forthcoming
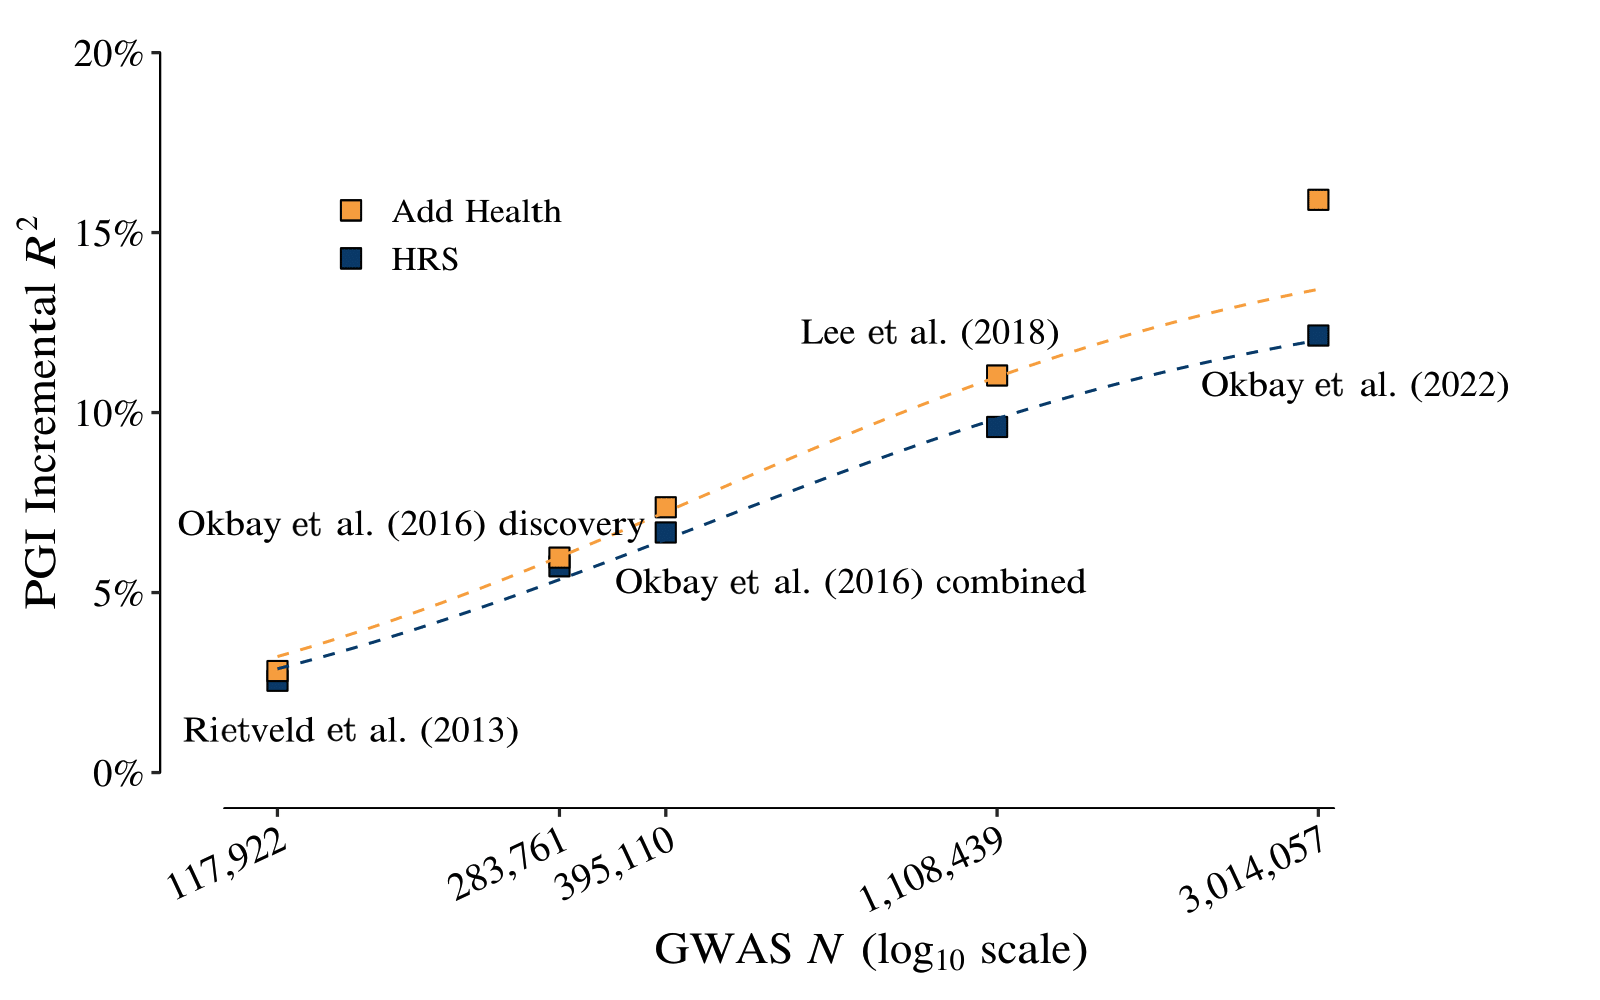
Rapid progress has been made in identifying links between human genetic variation and social and behavioral phenotypes. Applications in mainstream economics are beginning to emerge. This review aims to provide the background needed to bring the interested economist to the frontier of social-science genomics. Our review is structured around a statistical framework that nests many of the key methods, concepts and tools found in the literature. We clarify key assumptions and appropriate interpretations. After critically reviewing several significant applications, we conclude by outlining future advances in genetics that will enable more and improved applications, and we discuss the ethical and communication challenges that arise in this area of research.
-
 Family-GWAS reveals effects of environment and mating on genetic associationsTammy Tan, Hariharan Jayashankar, Junming Guan, and 73 more authorsmedRxiv, 2026Preprint; revised January 22, 2026
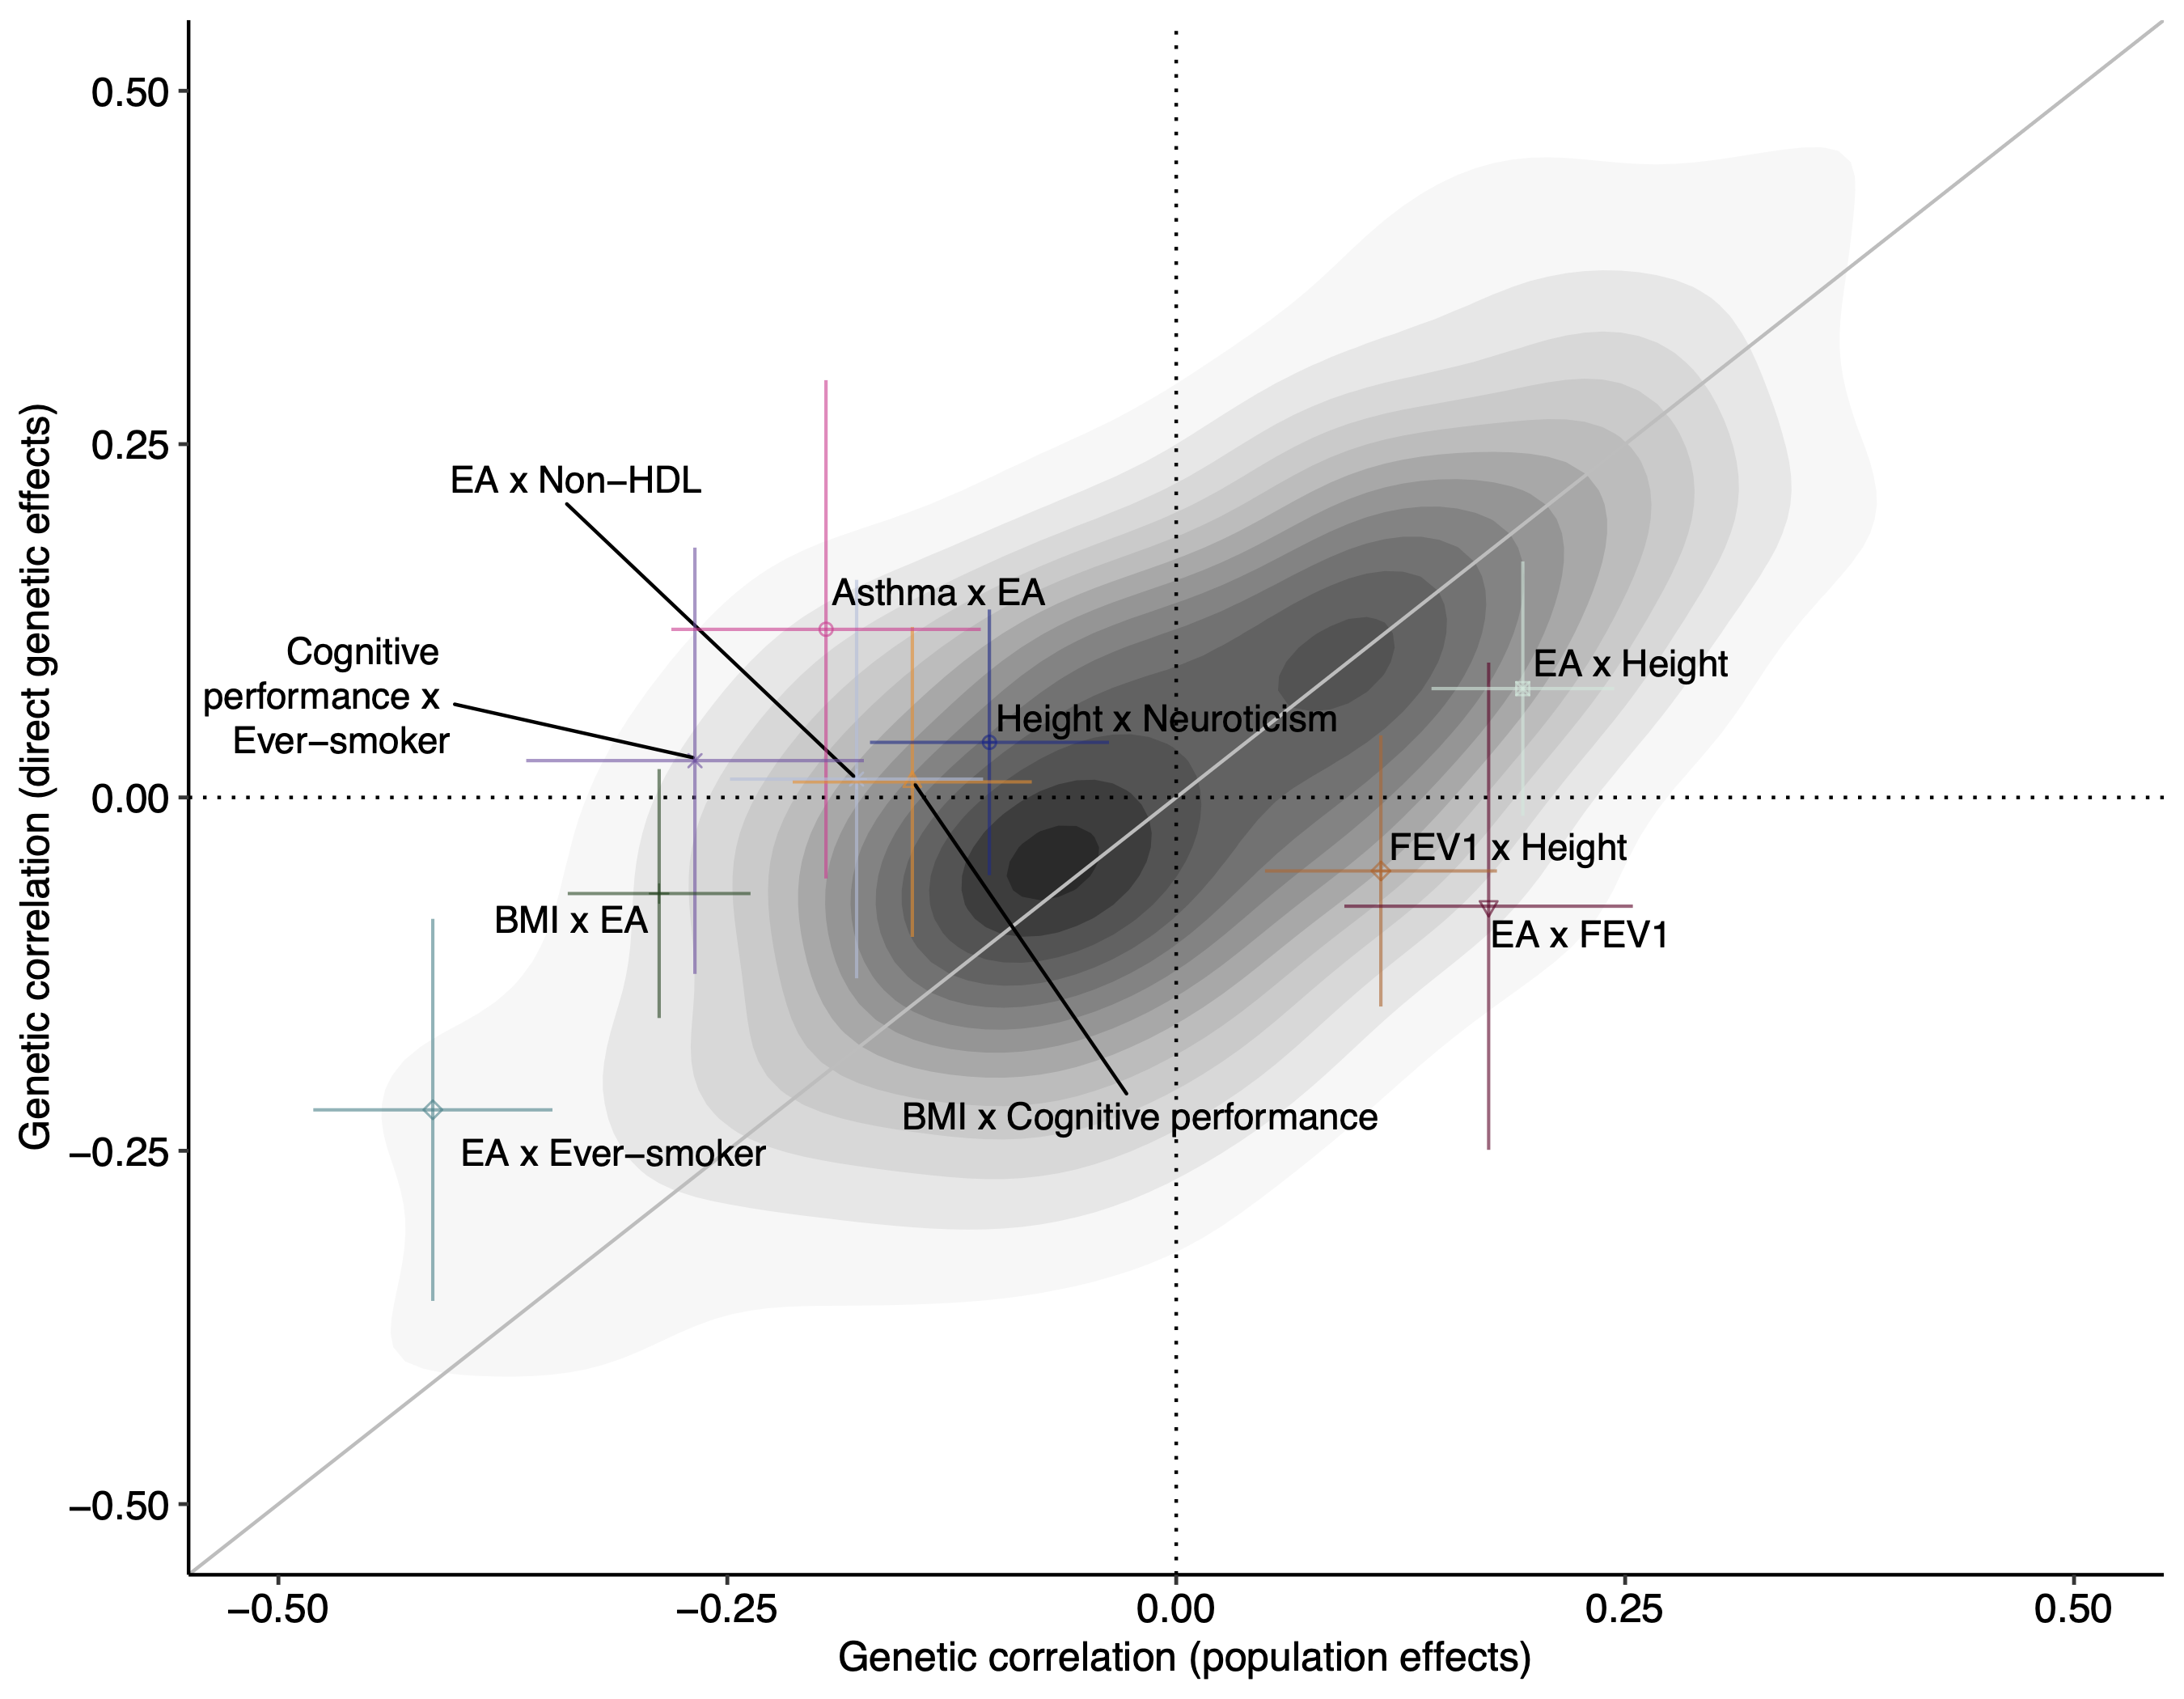
Genome-wide association studies (GWAS) have discovered thousands of replicable genetic associations, guiding drug target discovery and powering genetic prediction of human phenotypes and diseases. However, genetic associations can be affected by gene-environment correlations and non-random mating, which can lead to biased inferences in downstream analyses. Family-based GWAS (FGWAS) uses the natural experiment of random assignment of genotype within families to separate out the contribution of direct genetic effects (DGEs) — causal effects of alleles in an individual on an individual — from other factors contributing to genetic associations. Here, we report results from an FGWAS meta-analysis of 34 phenotypes from 17 cohorts. We found evidence that factors uncorrelated with DGEs make substantial contributions to genetic associations for 27 phenotypes, with population stratification confounding — a form of gene-environment correlation — likely the major cause. By estimating SNP heritability and genetic correlations using DGEs, we found evidence that assortative mating has led to overestimation of SNP heritability for 5 phenotypes and overestimation of the degree of shared genetic effects (pleiotropy) between 22 pairs of phenotypes. Polygenic predictors constructed from DGEs are particularly useful for studying natural selection, assortative mating, and indirect genetic effects (effects of relatives’ genes mediated through the family environment). We validate our meta-analysis results by predicting phenotypes in hold-out samples using polygenic predictors constructed from DGEs, achieving statistically significant out-of-sample prediction for 24 phenotypes with little attenuation of predictive power within-families. We provide FGWAS summary statistics for 34 phenotypes that can be used for downstream analyses. Our study provides both a template for performing FGWAS and an argument for its value for debiasing inferences and understanding the impact of environment and mating patterns.


2025
- An Updated Polygenic Index Repository: Expanded Phenotypes, New Cohorts, and Improved Causal InferenceRobel Alemu, Anastasia Terskaya, Matthew Howell, and 49 more authorsResearch Square, 2025Preprint
Polygenic indexes (PGIs) — DNA-based predictors of individual phenotypes — have become essential tools across biomedical and social sciences. We introduce Version 2 of the Polygenic Index Repository, which expands phenotype coverage from 47 to 61, increases the number of participating datasets from 11 to 20, and adopts a more consistent and improved methodology for PGI construction. For 16 phenotypes, we leverage summary statistics from an updated GWAS meta-analysis with greater statistical power compared to the original release, thereby improving the PGI’s predictive power. To improve power for family-based analyses, we provide imputed parental PGIs in all datasets with first-degree relatives and offer a framework for interpreting results from analyses that control for parental PGIs. We illustrate the utility of parental PGIs using two applications: (1) comparing PGI associations with and without parental PGI controls for all phenotypes in two Repository datasets with family data, and (2) for BMI and diastolic blood pressure, exploring the contribution of causal versus non-causal components of PGI associations to the imperfect portability of PGIs across subgroups within a genetic ancestry. Collectively, the updates enhance predictive performance, broaden the Repository’s scope, and introduce novel resources that reduce confounding bias and improve interpretability.
- Dissecting the Predictive Accuracy of Polygenic Indexes for Behavioral Phenotypes Across Genetic AncestriesRobel Alemu, Alexander S. Young, Daniel J. Benjamin, and 2 more authorsbioRxiv, 2025Preprint; revised March 28, 2026
Polygenic indexes (PGIs) trained on samples of European genetic ancestries often lose substantial predictive power when applied to non-European ancestries. While this portability problem is well recognized, its manifestation in behavioral and social traits remains understudied, and the factors driving this accuracy loss warrant more comprehensive analysis. Using data from the UK Biobank and Health and Retirement Study, we conduct a systematic analysis of PGI portability for 52 health-related, behavioral, and social phenotypes. We advance prior literature by using genome-wide PGIs, assessing cross-ancestry heritability differences, and comparing the performance of PGIs based on standard versus family-based GWAS. Our findings confirm systematic reductions in PGI predictive power for non-European ancestries—with relative accuracy being lowest in African (24%), followed by East Asian (37%) and South Asian (51%) genetic ancestries. We also find that biologically proximal traits exhibit greater portability than behavioral and social traits. We show that the relative importance of factors underlying reduced portability varies across traits and ancestries: in African ancestries, linkage disequilibrium and allele frequency differences explain most of the loss (82%), compared with smaller contributions in East (34%) and South Asian (25%) ancestries. Finally, we find that family-based GWAS PGIs can modestly improve portability for select traits, such as BMI in African ancestry, suggesting that part of the portability gap may reflect population-specific confounds in standard PGIs.
- Development and validation of polygenic scores for within-family prediction of disease risksSpencer Moore, Ivan Davidson, Jonathan Anomaly, and 7 more authorsmedRxiv, 2025Preprint
The clinical implementation of polygenic scores (PGSs) for disease risk prediction, particularly in reproductive health applications, requires rigorous validation. Here, we develop seventeen disease PGSs by conducting large-scale GWAS meta-analyses, and we validate our scores in out-of-sample prediction analyses. We achieve state-of-the-art predictive performance, consistently matching or outperforming academic and commercial benchmarks, with liability R² reaching up to 0.21 (type 2 diabetes). The performance of a PGS for embryo screening depends on its predictive ability within-family, which can be lower than its prediction ability among unrelated individuals. However, very few disease PGSs have been tested within-family. We perform systematic within-family validation of our disease PGSs, finding no decrease in predictive performance within-family for 16 of 17 scores. PGS performance typically declines with genetic distance from training data, an effect that needs to be accounted for to give properly calibrated predictions across ancestries. We perform extensive calibration of our scores’ performance across different ancestries, finding improved cross-ancestry performance compared to previous approaches, especially in African and East Asian populations. This is likely due to the fact our scores are constructed using a method that incorporates functional genomic annotations on more than 7 million variants, enabling a degree of fine-mapping of causal variants shared across ancestries. We illustrate clinical utility through examining the risk reduction that could be achieved through embryo screening for type 2 diabetes: selecting among 10 embryos is expected to reduce absolute disease risk by 12-20% in families where both parents are affected, with similar relative risk reductions across ancestries. These findings establish a framework for implementing PGS in reproductive medicine while demonstrating both the technology’s potential for disease prevention and the methodological standards required for responsible clinical translation.
-
 ImputePGTA: accurate embryo genotyping and polygenic scoring from ultra-low-pass sequencingJeremiah H Li, Tobias Wolfram, Ivan Davidson, and 6 more authorsmedRxiv, 2025Preprint; revised February 2026
Preimplantation genetic testing (PGT) for polygenic risk (PGT-P) holds great promise for reducing lifetime disease burden, but genotyping embryos remains difficult. PGT for aneuploidy (PGT-A) is a routine test used in over half of in vitro fertilization cycles in the United States, typically via ultra-low-pass (ULP) sequencing (∼0.004x) or, less commonly, genotyping arrays. Here we describe an approach that enables accurate embryo genotyping from PGT-A data when combined with estimated parental haplotypes. We develop a Coupled Hidden Markov Model, ImputePGTA, which jointly infers inheritance patterns from parents to offspring as well as phasing errors in parental haplotypes, along with an inference algorithm that scales linearly with the number of embryos. The performance of our approach depends on the phasing of parental haplotypes, which we improve through a method, phaseGrafter, that combines evidence from short and long reads, further enabling imputation of rare variants. We validate our approach through simulations and comparison of embryo genomes reconstructed from real PGT-A data to post-birth whole genome sequencing data. When using long reads for parental phasing, we achieve a dosage correlation of 0.98 with high-quality post-birth genotypes, and a mean absolute difference of 0.11 standard deviations across 17 disease polygenic scores, lower than from imputation of genotyping array data from reference panels. Uncertainty from imputation from ULP PGT-A data with accurate parental phasing results in only a ∼2% attenuation in expected gains from embryo selection for typical embryo cohort sizes. Our approach removes an important technological barrier to using PGT-P and is already facilitating more widespread adoption.
-
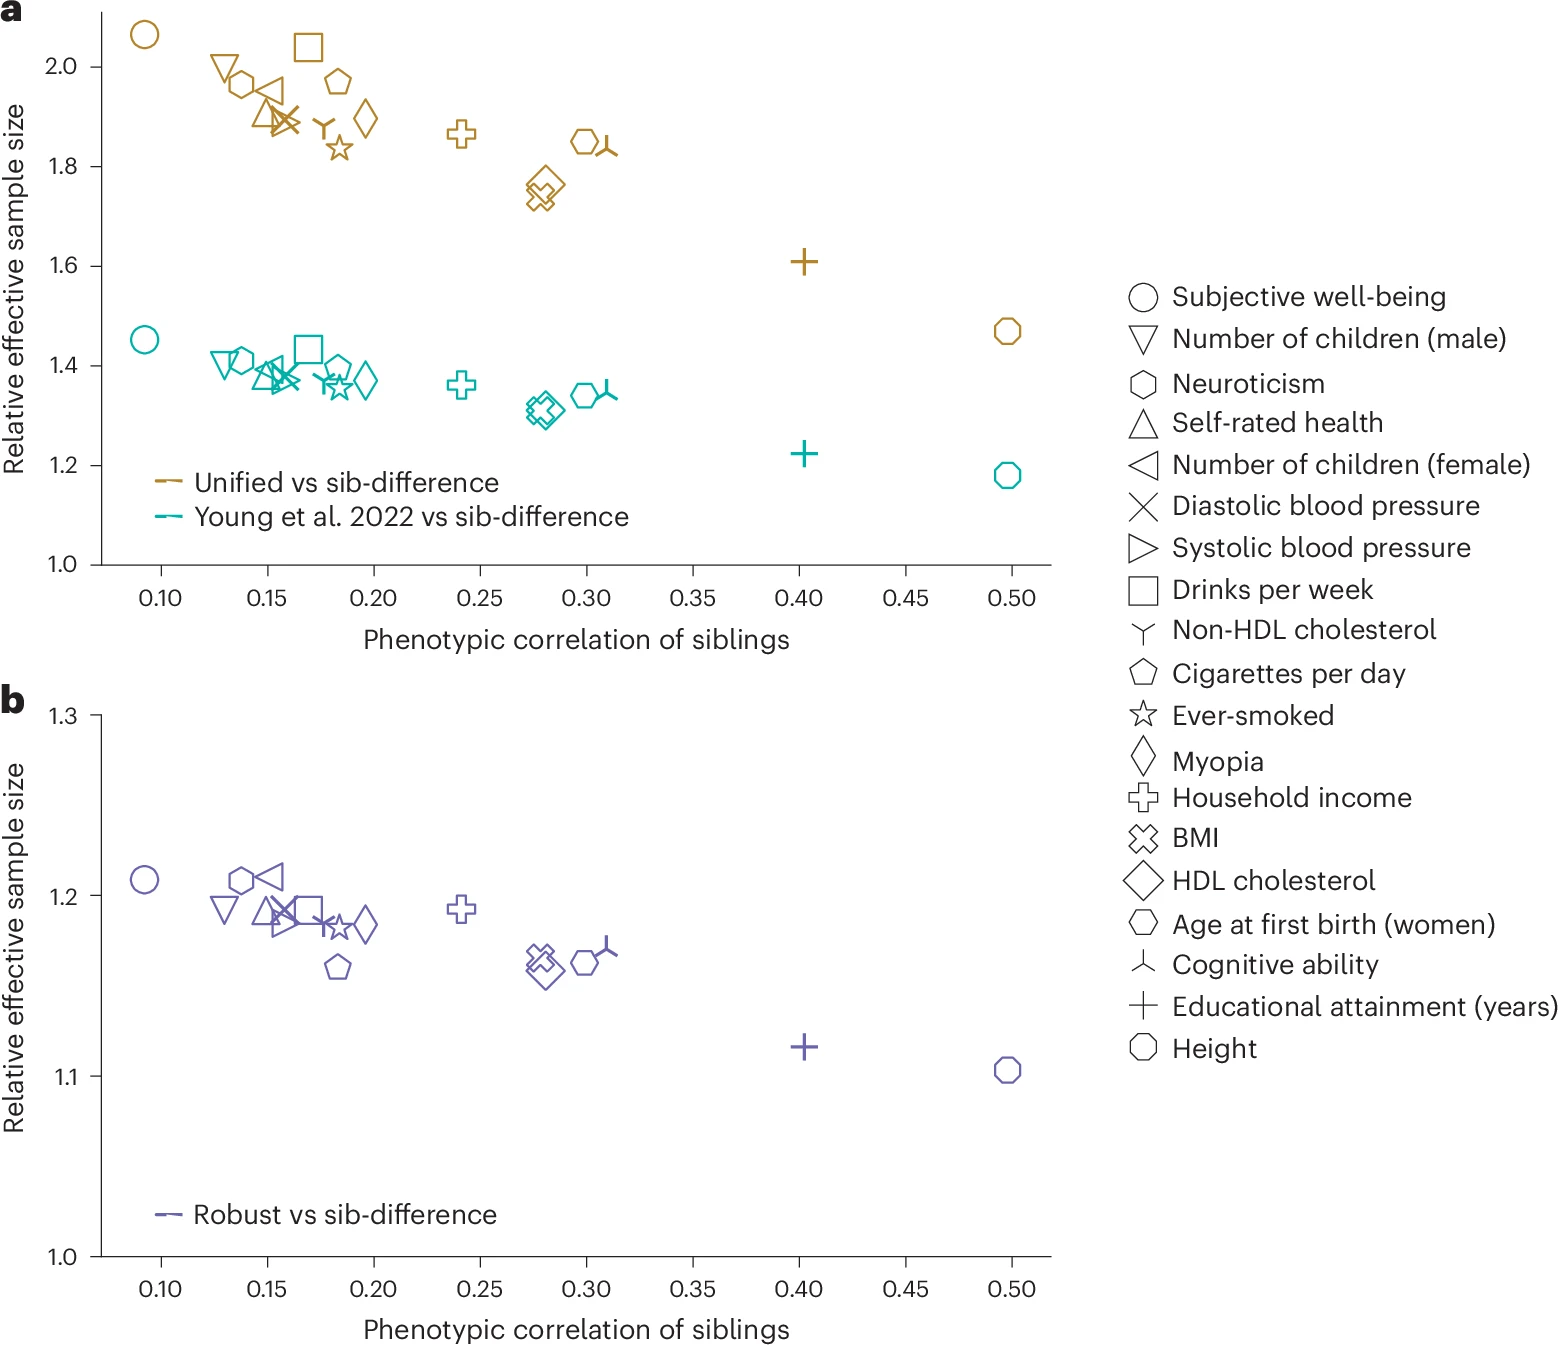 Family-based genome-wide association study designs for increased power and robustnessJunming Guan, Tammy Tan, Seyed Moeen Nehzati, and 4 more authorsNature Genetics, 2025
Family-based genome-wide association studies (FGWASs) use random, within-family genetic variation to remove confounding from estimates of direct genetic effects (DGEs). Here we introduce a ‘unified estimator’ that includes individuals without genotyped relatives, unifying standard and FGWAS while increasing power for DGE estimation. We also introduce a ‘robust estimator’ that is not biased in structured and/or admixed populations. In an analysis of 19 phenotypes in the UK Biobank, the unified estimator in the White British subsample and the robust estimator (applied without ancestry restrictions) increased the effective sample size for DGEs by 46.9% to 106.5% and 10.3% to 21.0%, respectively, compared to using genetic differences between siblings. Polygenic predictors derived from the unified estimator demonstrated superior out-of-sample prediction ability compared to other family-based methods. We implemented the methods in the software package snipar in an efficient linear mixed model that accounts for sample relatedness and sibling shared environment.


2024
- Examining the role of common variants in rare neurodevelopmental conditionsQin Qin Huang, Emilie M. Wigdor, Daniel S. Malawsky, and 18 more authorsNature, 2024
Although rare neurodevelopmental conditions have a large Mendelian component, common genetic variants also contribute to risk. However, little is known about how this polygenic risk is distributed among patients with these conditions and their parents nor its interplay with rare variants. It is also unclear whether polygenic background affects risk directly through alleles transmitted from parents to children, or whether indirect genetic effects mediated through the family environment also play a role. Here we addressed these questions using genetic data from 11,573 patients with rare neurodevelopmental conditions, 9,128 of their parents and 26,869 controls. Common variants explained around 10% of variance in risk. Patients with a monogenic diagnosis had significantly less polygenic risk than those without, supporting a liability threshold model. A polygenic score for neurodevelopmental conditions showed only a direct genetic effect. By contrast, polygenic scores for educational attainment and cognitive performance showed no direct genetic effect, but the non-transmitted alleles in the parents were correlated with the child’s risk, potentially due to indirect genetic effects and/or parental assortment for these traits. Indeed, as expected under parental assortment, we show that common variant predisposition for neurodevelopmental conditions is correlated with the rare variant component of risk. These findings indicate that future studies should investigate the possible role and nature of indirect genetic effects on rare neurodevelopmental conditions, and consider the contribution of common and rare variants simultaneously when studying cognition-related phenotypes.
- The importance of family-based sampling for biobanksNeil M. Davies, Gibran Hemani, Jenae M. Neiderhiser, and 6 more authorsNature, 2024
Biobanks aim to improve our understanding of health and disease by collecting and analysing diverse biological and phenotypic information in large samples. So far, biobanks have largely pursued a population-based sampling strategy, where the individual is the unit of sampling, and familial relatedness occurs sporadically and by chance. This strategy has been remarkably efficient and successful, leading to thousands of scientific discoveries across multiple research domains, and plans for the next wave of biobanks are underway. In this Perspective, we discuss the strengths and limitations of a complementary sampling strategy for future biobanks based on oversampling of close genetic relatives. Such family-based samples facilitate research that clarifies causal relationships between putative risk factors and outcomes, particularly in estimates of genetic effects, because they enable analyses that reduce or eliminate confounding due to familial and demographic factors. Family-based biobank samples would also shed new light on fundamental questions across multiple fields that are often difficult to explore in population-based samples. Despite the potential for higher costs and greater analytical complexity, the many advantages of family-based samples should often outweigh their potential challenges.
- Genome-wide association studies have problems due to confounding: Are family-based designs the answer?Alexander Strudwick YoungPLOS Biology, 2024
Genome-wide association studies (GWASs) can be affected by confounding. Family-based GWAS uses random, within-family genetic variation to avoid this. A study in PLOS Biology details how different sources of confounding affect GWAS and whether family-based designs offer a solution.
- Simple models of non-random mating and environmental transmission bias standard human genetics statistical methodsRichard Border, Jeremy Wang, Christa Caggiano, and 7 more authorsbioRxiv, 2024Preprint; accepted at Nature Genetics
There is recognition among human complex-trait geneticists that not only are many common assumptions made for the sake of statistical tractability (e.g., random mating, independence of parent/offspring environments) unlikely to apply in many contexts, but that methods reliant on such assumptions can yield misleading results, even in large samples. Investigations of the consequences of violating these assumptions so far have focused on individual perturbations operating in isolation. Here, we analyze widely used estimators of genetic architectural parameters, including LD-score regression and both population-based and within-family GWAS, across a broad array of perturbations to classical assumptions, such as multivariate assortative mating and vertical transmission (parental effects on offspring phenotypes not mediated by genetic inheritance). We find that widely-used statistical approaches are unreliable across a broad range of perturbations, and that structural sources of confounding often operate synergistically to distort conclusions. For example, mild multivariate assortative mating and vertical transmission together can dramatically inflate heritability estimates and GWAS false positive rates. Further, GWAS will become progressively more polluted by off-target associations as sample sizes increase. Given these challenges, we introduce xftsim, a forward time simulation library capable of modeling a wide range of genetic architectures, mating regimes, and transmission dynamics, to facilitate the systematic comparison of existing approaches and the development of robust methods. Together, our findings illustrate the importance of comprehensive sensitivity analysis and present a valuable tool for future research.
2023
-
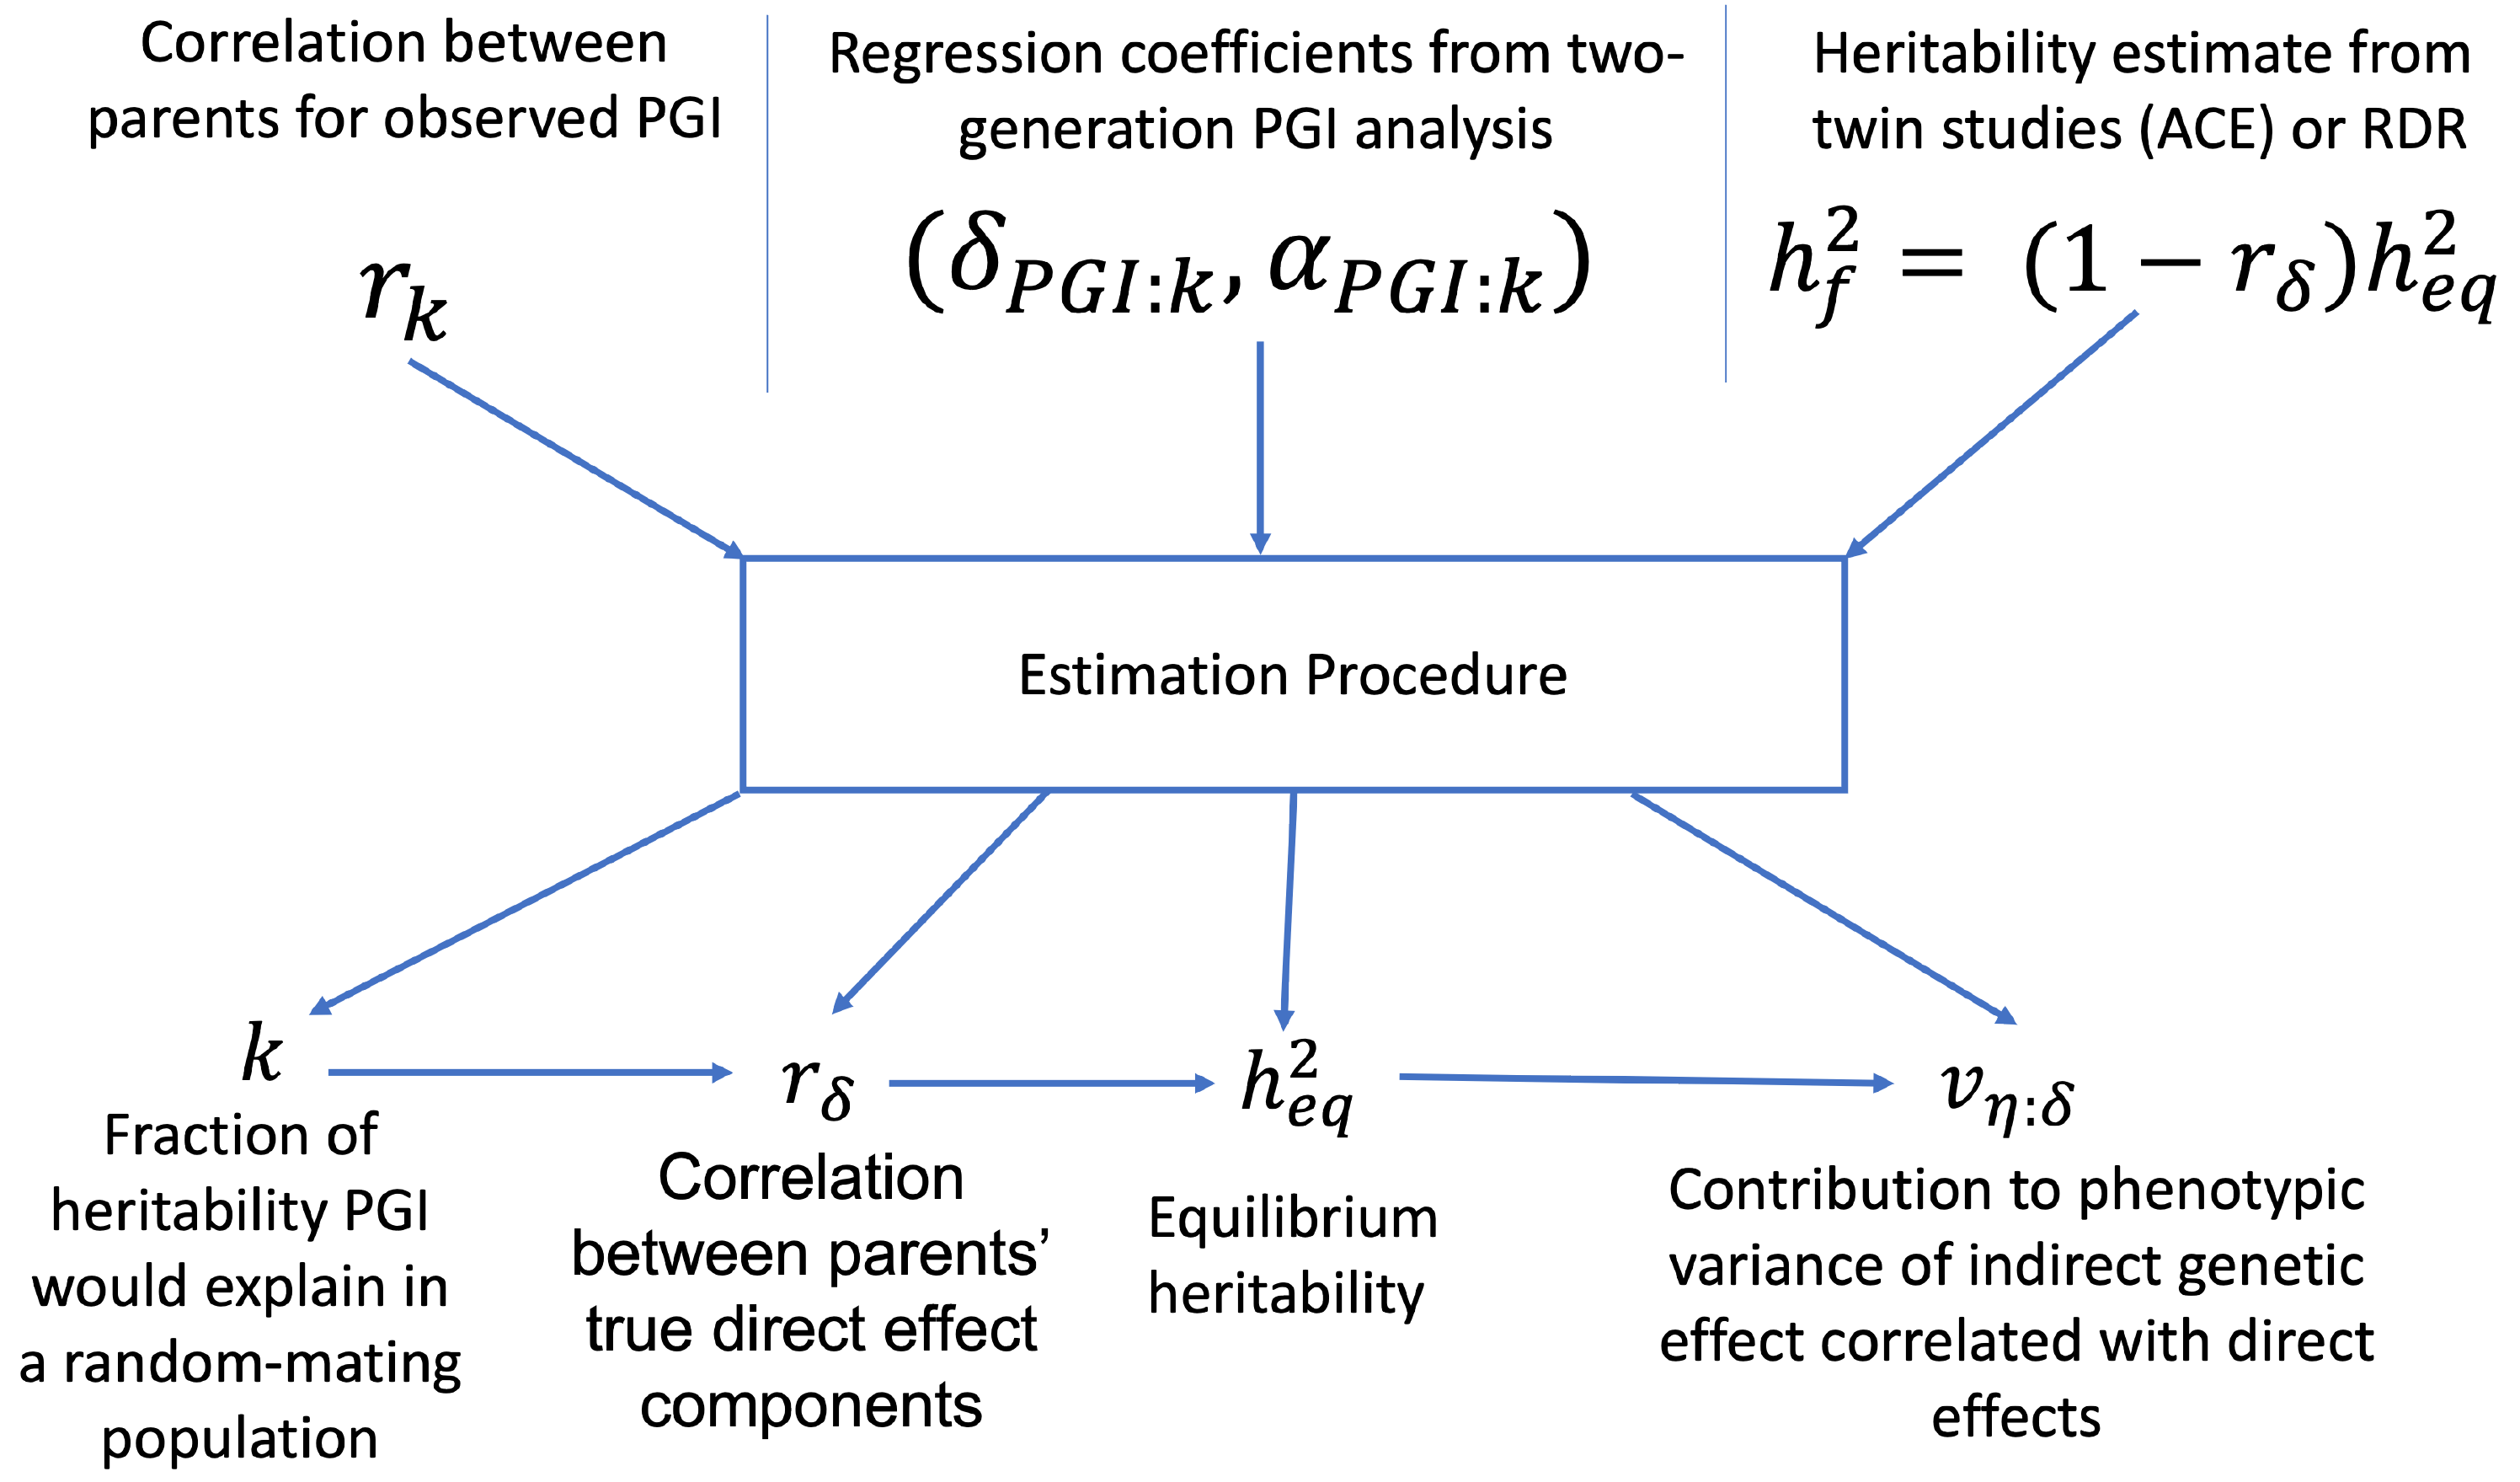 Estimation of indirect genetic effects and heritability under assortative matingAlexander Strudwick YoungbioRxiv, 2023
Both direct genetic effects (effects of alleles in an individual on that individual) and indirect genetic effects — effects of alleles in an individual (e.g. parents) on another individual (e.g. offspring) — can contribute to phenotypic variation and genotype-phenotype associations. Here, we consider a phenotype affected by direct and parental indirect genetic effects under assortative mating at equilibrium. We generalize classical theory to derive a decomposition of the equilibrium phenotypic variance in terms of direct and indirect genetic effect components. We extend this theory to show that popular methods for estimating indirect genetic effects or ‘genetic nurture’ through analysis of parental and offspring polygenic predictors (called polygenic indices or scores — PGIs or PGSs) are substantially biased by assortative mating. We propose an improved method for estimating indirect genetic effects while accounting for assortative mating that can also correct heritability estimates for bias due to assortative mating. We validate our method in simulations and apply it to PGIs for height and educational attainment (EA), estimating that the equilibrium heritability of height is 0.699 (S.E. = 0.075) and finding no evidence for indirect genetic effects on height. We estimate a very high correlation between parents’ underlying genetic components for EA, 0.755 (S.E. = 0.035), which is inconsistent with twin based estimates of the heritability of EA, possibly due to confounding in the EA PGI and/or in twin studies. We implement our method in the software package snipar, enabling researchers to apply the method to data including observed and/or imputed parental genotypes. We provide a theoretical framework for understanding the results of PGI analyses and a practical methodology for estimating heritability and indirect genetic effects while accounting for assortative mating.
- Discovering genes that affect cognitive abilityAlexander Strudwick Young, and Hilary C MartinTrends in Genetics, 2023
Twin and genomic studies indicate that genes play an important role in the development of cognitive ability. However, data limitations have made it difficult to pinpoint specific genes with a large impact. By examining the full gene sequences of >300 000 individuals, Chen et al. find eight such genes.

2022
-
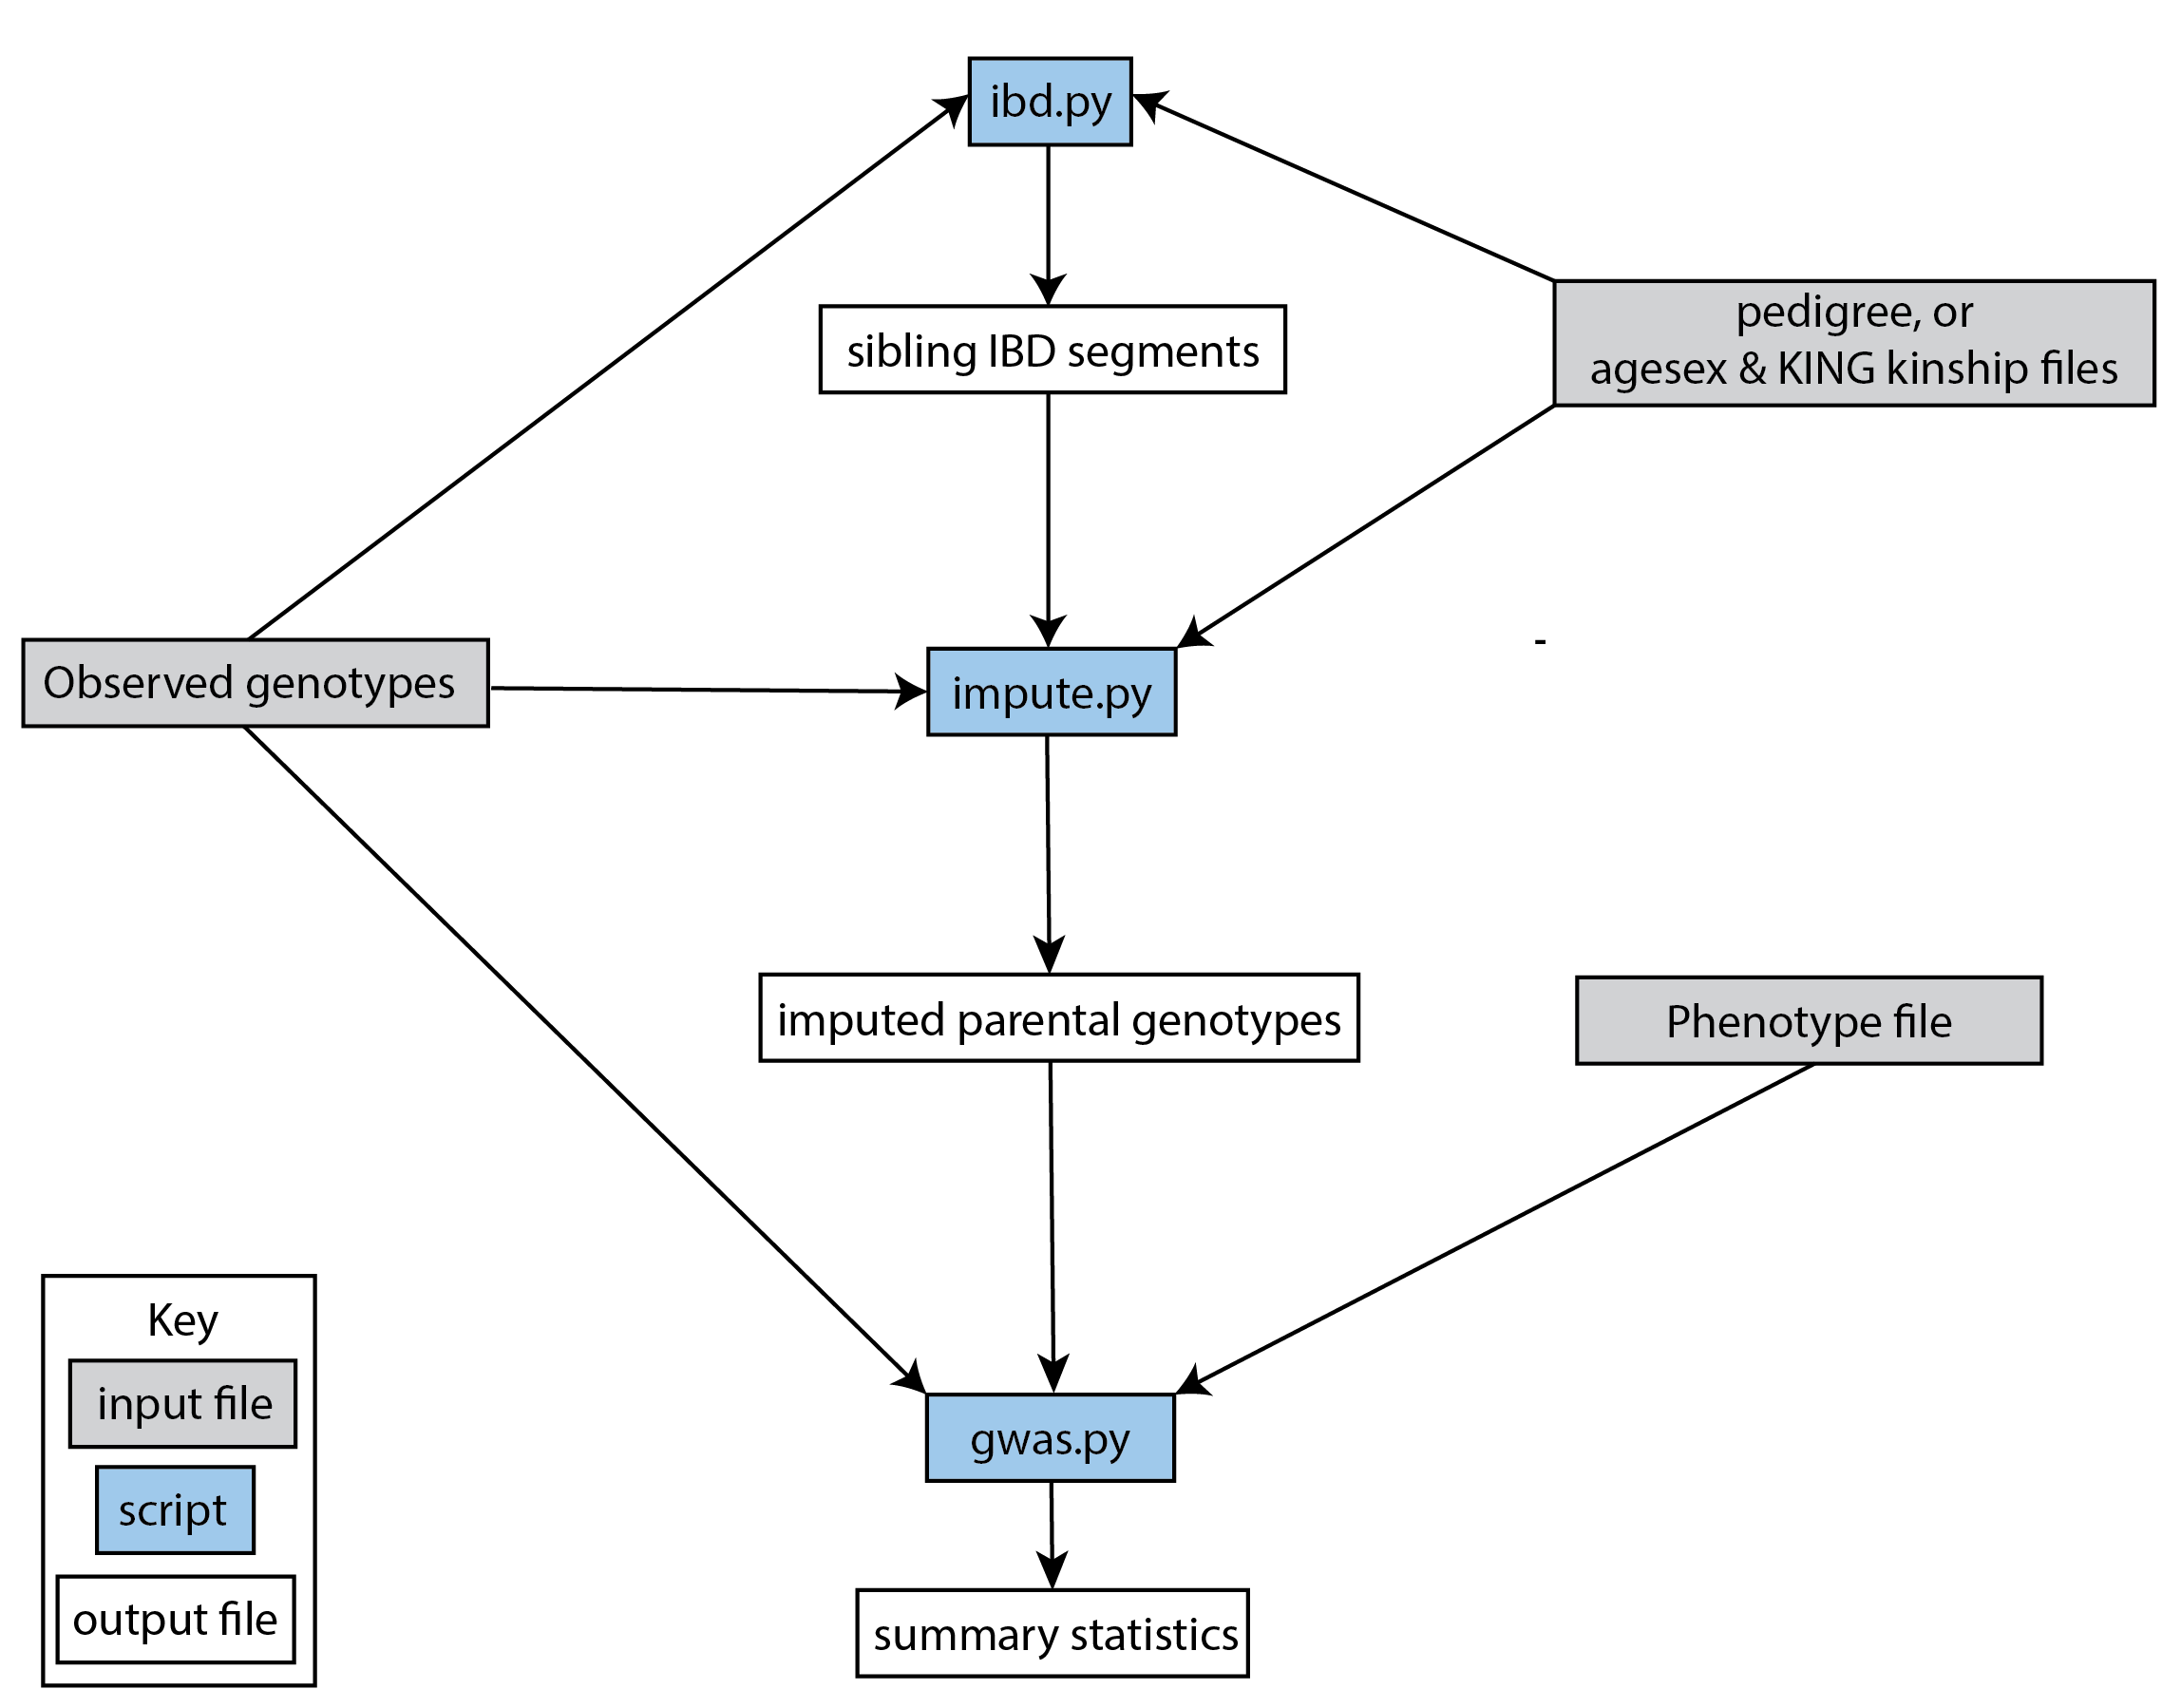 Mendelian imputation of parental genotypes improves estimates of direct genetic effectsAlexander Strudwick Young, Seyed Moeen Nehzati, Stefania Benonisdottir, and 7 more authorsNature genetics, 2022
Effects estimated by genome-wide association studies (GWASs) include effects of alleles in an individual on that individual (direct genetic effects), indirect genetic effects (for example, effects of alleles in parents on offspring through the environment) and bias from confounding. Within-family genetic variation is random, enabling unbiased estimation of direct genetic effects when parents are genotyped. However, parental genotypes are often missing. We introduce a method that imputes missing parental genotypes and estimates direct genetic effects. Our method, implemented in the software package snipar (single-nucleotide imputation of parents), gives more precise estimates of direct genetic effects than existing approaches. Using 39,614 individuals from the UK Biobank with at least one genotyped sibling/parent, we estimate the correlation between direct genetic effects and effects from standard GWASs for nine phenotypes, including educational attainment (r = 0.739, standard error (s.e.) = 0.086) and cognitive ability (r = 0.490, s.e. = 0.086). Our results demonstrate substantial confounding bias in standard GWASs for some phenotypes.
-
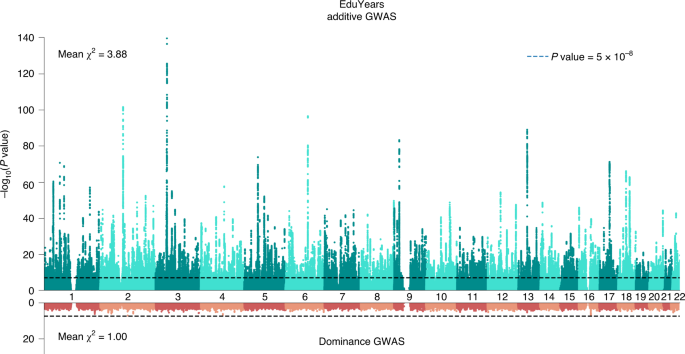 Polygenic prediction of educational attainment within and between families from genome-wide association analyses in 3 million individualsAysu Okbay, Yeda Wu, Nancy Wang, and 8 more authorsNature genetics, 2022
We conduct a genome-wide association study (GWAS) of educational attainment (EA) in a sample of ∼3 million individuals and identify 3,952 approximately uncorrelated genome-wide-significant single-nucleotide polymorphisms (SNPs). A genome-wide polygenic predictor, or polygenic index (PGI), explains 12–16% of EA variance and contributes to risk prediction for ten diseases. Direct effects (i.e., controlling for parental PGIs) explain roughly half the PGI’s magnitude of association with EA and other phenotypes. The correlation between mate-pair PGIs is far too large to be consistent with phenotypic assortment alone, implying additional assortment on PGI-associated factors. In an additional GWAS of dominance deviations from the additive model, we identify no genome-wide-significant SNPs, and a separate X-chromosome additive GWAS identifies 57.
- Discovering missing heritability in whole-genome sequencing dataAlexander I YoungNature Genetics, 2022
The gap between heritability estimates from twin studies and those from genotyping array data has puzzled researchers for over a decade. New research suggests that much of the ‘missing’ heritability is due to rare variants that can only be captured by whole-genome sequencing (WGS) data.
- Novel estimators for family-based genome-wide association studies increase power and robustnessJunming Guan, Seyed Moeen Nehzati, Daniel J Benjamin, and 1 more authorbioRxiv, 2022Preprint
A goal of genome-wide association studies (GWASs) is to estimate the causal effects of alleles carried by an individual on that individual ( direct genetic effects). Typical GWAS designs, however, are susceptible to confounding due to gene-environment correlation and non-random mating (population stratification and assortative mating). Family-based GWAS, in contrast, is robust to such confounding since it uses random, within-family genetic variation. When both parents are genotyped, a regression controlling for parental genotype provides the most powerful approach. However, parental genotypes are often missing. We have previously shown that imputing the genotypes of missing parent(s) can increase power for estimation of direct genetic effects over using genetic differences between siblings. We extend the imputation method, which previously only applied to samples with at least one genotyped sibling or parent, to singletons (individuals without any genotyped relatives). By including singletons, the effective sample size for estimation of direct effects can be increased by up to 50%. We apply this method to 408,254 White British individuals from the UK Biobank, obtaining an effective sample size increase of between 25% and 43% (depending upon phenotype) by including 368,629 singletons. While this approach maximizes power, it can be biased when there is strong population structure. We therefore introduce an imputation based estimator that is robust to population structure and more powerful than other robust estimators. We implement our estimators in the software package snipar using an efficient linear-mixed model (LMM) specified by a sparse genetic relatedness matrix. We examine the bias and variance of different family-based and standard GWAS estimators theoretically and in simulations with differing levels of population structure, enabling researchers to choose the appropriate approach depending on their research goals.
- Cross-trait assortative mating is widespread and inflates genetic correlation estimatesRichard Border, Georgios Athanasiadis, Alfonso Buil, and 8 more authorsScience, 2022
The observation of genetic correlations between disparate human traits has been interpreted as evidence of widespread pleiotropy. Here, we introduce cross-trait assortative mating (xAM) as an alternative explanation. We observe that xAM affects many phenotypes and that phenotypic cross-mate correlation estimates are strongly associated with genetic correlation estimates (R²=74%). We demonstrate that existing xAM plausibly accounts for substantial fractions of genetic correlation estimates and that previously reported genetic correlation estimates between some pairs of psychiatric disorders are congruent with xAM alone. Finally, we provide evidence for a history of xAM at the genetic level using cross-trait even/odd chromosome polygenic score correlations. Together, our results demonstrate that previous reports have likely overestimated the true genetic similarity between many phenotypes.


2021
- Resource profile and user guide of the Polygenic Index RepositoryJoel Becker, Casper AP Burik, Grant Goldman, and 8 more authorsNature human behaviour, 2021
Polygenic indexes (PGIs) are DNA-based predictors. Their value for research in many scientific disciplines is growing rapidly. As a resource for researchers, we used a consistent methodology to construct PGIs for 47 phenotypes in 11 datasets. To maximize the PGIs’ prediction accuracies, we constructed them using genome-wide association studies-some not previously published-from multiple data sources, including 23andMe and UK Biobank. We present a theoretical framework to help interpret analyses involving PGIs. A key insight is that a PGI can be understood as an unbiased but noisy measure of a latent variable we call the ’additive SNP factor’. Regressions in which the true regressor is this factor but the PGI is used as its proxy therefore suffer from errors-in-variables bias. We derive an estimator that corrects for the bias, illustrate the correction, and make a Python tool for implementing it publicly available.
2020
- How important are parents in the development of child anxiety and depression? A genomic analysis of parent-offspring trios in the Norwegian Mother Father and Child Cohort Study (MoBa)Rosa Cheesman, Espen Moen Eilertsen, Yasmin I Ahmadzadeh, and 8 more authorsBMC medicine, 2020
Background: Many studies detect associations between parent behaviour and child symptoms of anxiety and depression. Despite knowledge that anxiety and depression are influenced by a complex interplay of genetic and environmental risk factors, most studies do not account for shared familial genetic risk. Quantitative genetic designs provide a means of controlling for shared genetics, but rely on observed putative exposure variables, and require data from highly specific family structures. Methods: The intergenerational genomic method, Relatedness Disequilibrium Regression (RDR), indexes environmental effects of parents on child traits using measured genotypes. RDR estimates how much the parent genome influences the child indirectly via the environment, over and above effects of genetic factors acting directly in the child. This ’genetic nurture’ effect is agnostic to parent phenotype and captures unmeasured heritable parent behaviours. We applied RDR in a sample of 11,598 parent-offspring trios from the Norwegian Mother, Father and Child Cohort Study (MoBa) to estimate parental genetic nurture separately from direct child genetic effects on anxiety and depression symptoms at age 8. We tested for mediation of genetic nurture via maternal anxiety and depression symptoms. Results were compared to a complementary non-genomic pedigree model. Results: Parental genetic nurture explained 14% of the variance in depression symptoms at age 8. Subsequent analyses suggested that maternal anxiety and depression partially mediated this effect. The genetic nurture effect was mirrored by the finding of family environmental influence in our pedigree model. In contrast, variance in anxiety symptoms was not significantly influenced by common genetic variation in children or parents, despite a moderate pedigree heritability. Conclusions: Genomic methods like RDR represent new opportunities for genetically sensitive family research on complex human traits, which until now has been largely confined to adoption, twin and other pedigree designs. Our results are relevant to debates about the role of parents in the development of anxiety and depression in children, and possibly where to intervene to reduce problems.
- Family analysis with Mendelian imputationsAugustine Kong, Stefania Benonisdottir, and Alexander I YoungBioRxiv, 2020Preprint; revised July 8, 2020
Genotype-phenotype associations can be results of direct effects, genetic nurturing effects and population stratification confounding. Genotypes from parents and siblings of the proband can be used to statistically disentangle these effects. To maximize power, a comprehensive framework for utilizing various combinations of parents’ and siblings’ genotypes is introduced. Central to the approach is mendelian imputation , a method that utilizes identity by descent (IBD) information to non-linearly impute genotypes into untyped relatives using genotypes of typed individuals. Applying the method to UK Biobank probands with at least one parent or sibling genotyped, for an educational attainment (EA) polygenic score that has an R² of 5.7% with EA, its predictive power based on direct genetic effect alone is demonstrated to be only about 1.4%. For women, the EA polygenic score has a bigger estimated direct effect on age-at-first-birth than EA itself.
2019
-
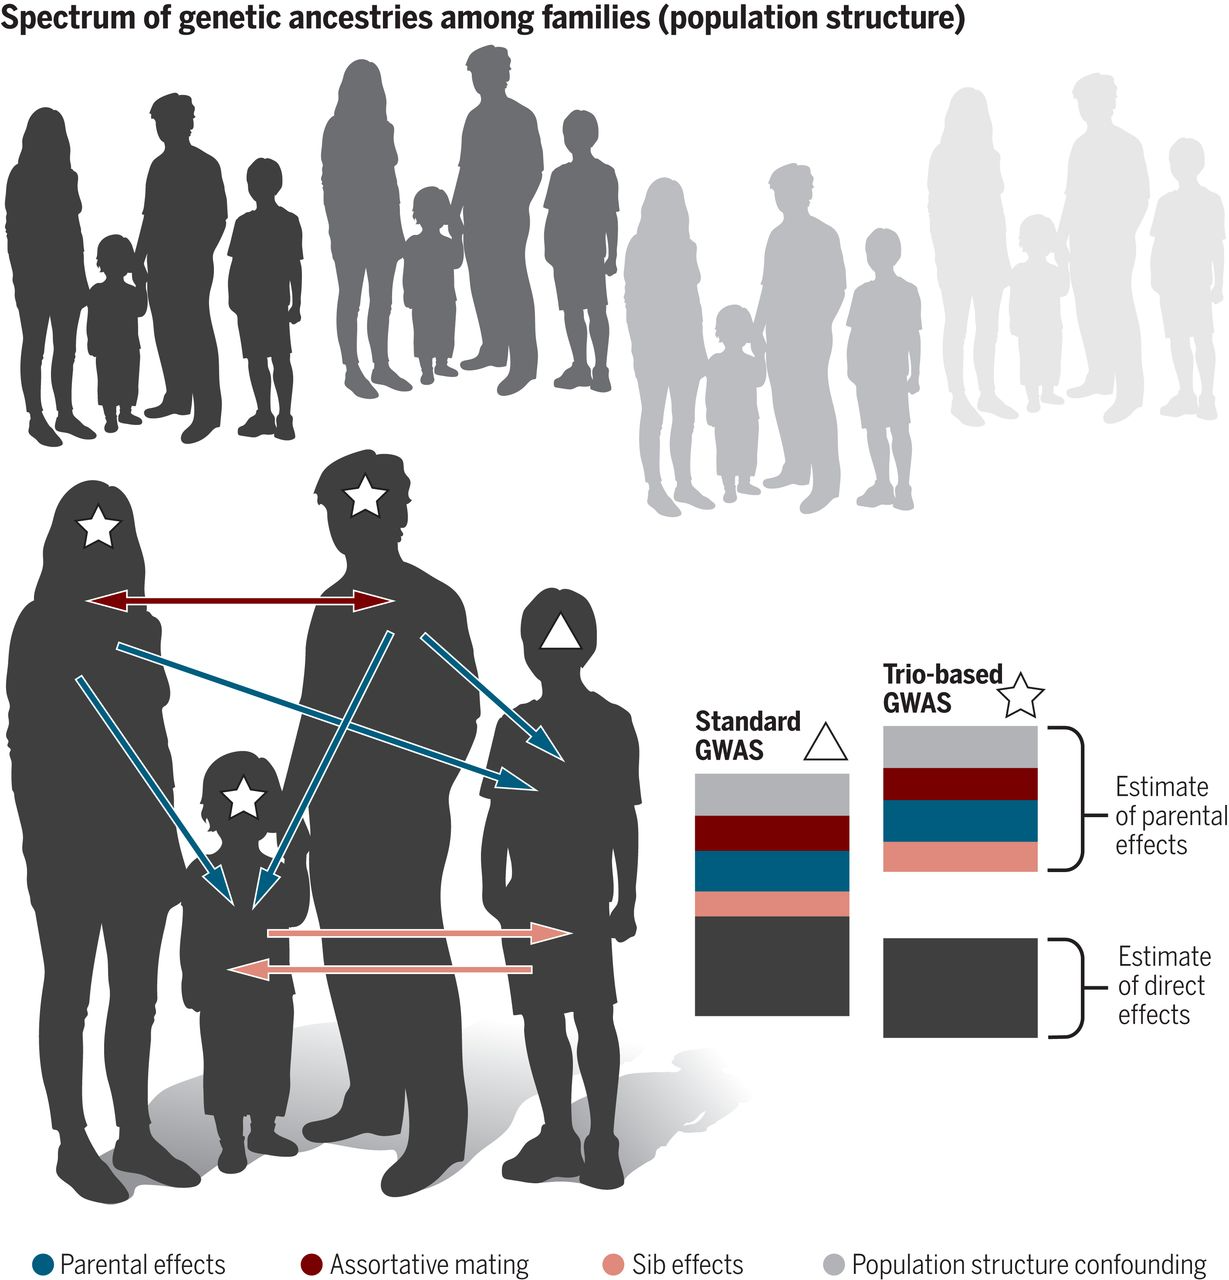 Deconstructing the sources of genotype-phenotype associations in humansAlexander Strudwick Young, Stefania Benonisdottir, Molly Przeworski, and 1 more authorScience, 2019
Efforts to link variation in the human genome to phenotypes have progressed at a tremendous pace in recent decades. Most human traits have been shown to be affected by a large number of genetic variants across the genome. To interpret these associations and to use them reliably—in particular for phenotypic prediction—a better understanding of the many sources of genotype-phenotype associations is necessary. We summarize the progress that has been made in this direction in humans, notably in decomposing direct and indirect genetic effects as well as population structure confounding. We discuss the natural next steps in data collection and methodology development, with a focus on what can be gained by analyzing genotype and phenotype data from close relatives.


2018
-
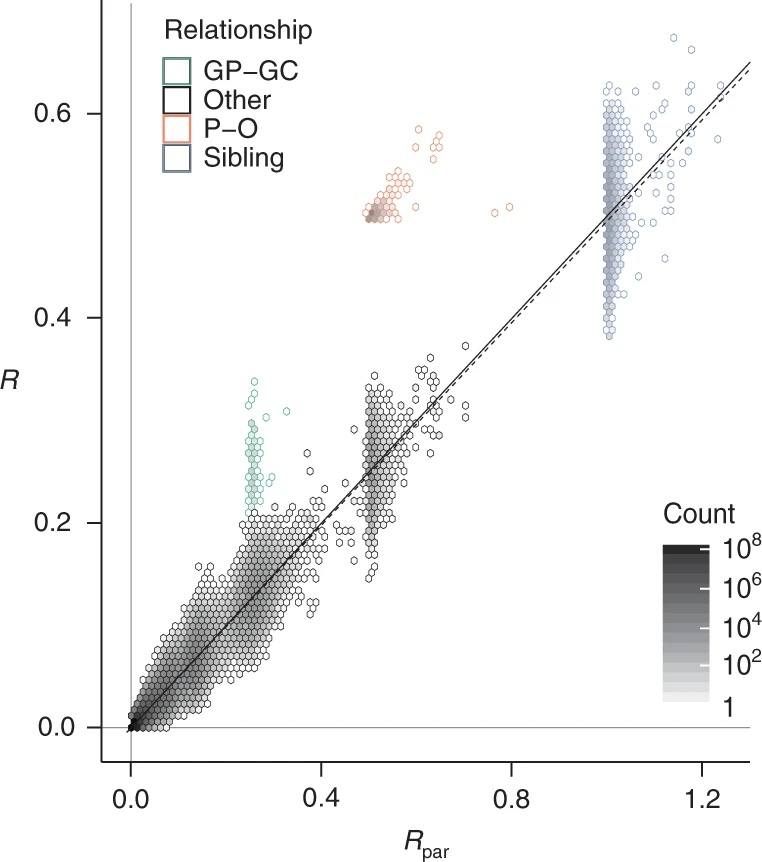 Relatedness disequilibrium regression estimates heritability without environmental biasAlexander Strudwick Young, Michael L Frigge, Daniel F Gudbjartsson, and 7 more authorsNature genetics, 2018
Heritability measures the proportion of trait variation that is due to genetic inheritance. Measurement of heritability is important in the nature-versus-nurture debate. However, existing estimates of heritability may be biased by environmental effects. Here, we introduce relatedness disequilibrium regression (RDR), a novel method for estimating heritability. RDR avoids most sources of environmental bias by exploiting variation in relatedness due to random Mendelian segregation. We used a sample of 54,888 Icelanders who had both parents genotyped to estimate the heritability of 14 traits, including height (55.4%, s.e. 4.4%) and educational attainment (17.0%, s.e. 9.4%). Our results suggest that some other estimates of heritability may be inflated by environmental effects.
-
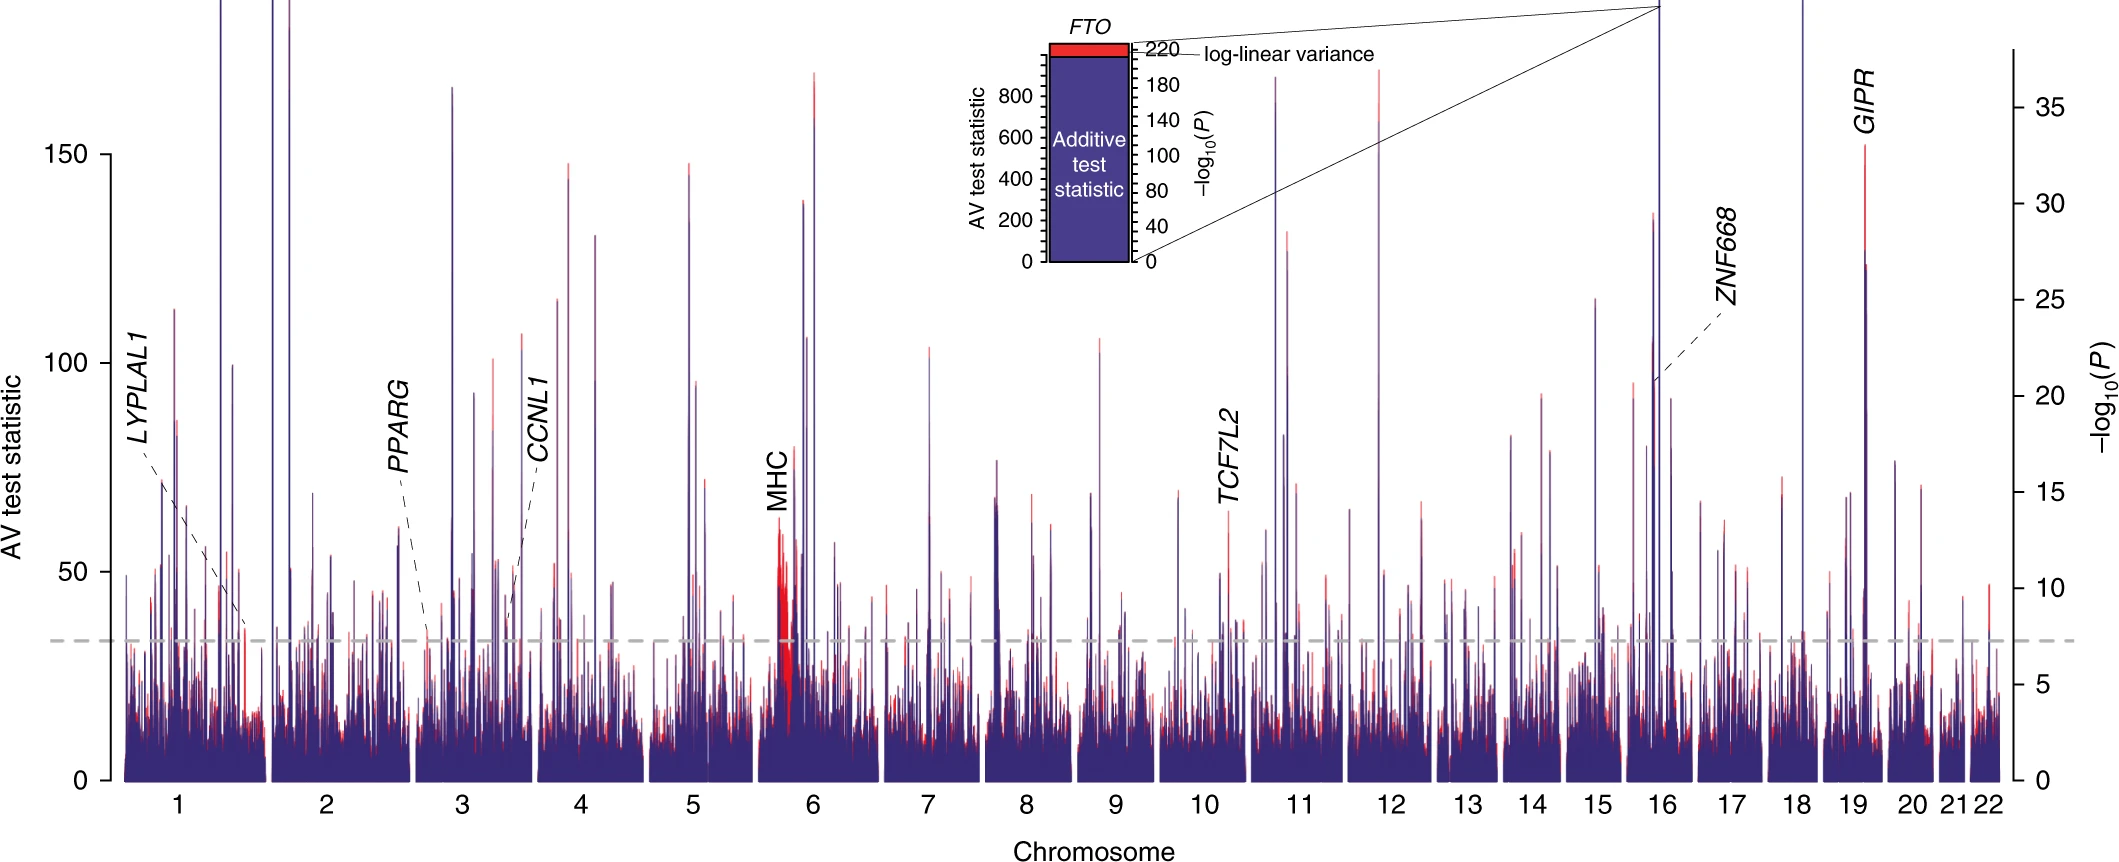 Identifying loci affecting trait variability and detecting interactions in genome-wide association studiesAlexander Strudwick Young, Fabian L Wauthier, and Peter DonnellyNature genetics, 2018
Identification of genetic variants with effects on trait variability can provide insights into the biological mechanisms that control variation and can identify potential interactions. We propose a two-degree-of-freedom test for jointly testing mean and variance effects to identify such variants. We implement the test in a linear mixed model, for which we provide an efficient algorithm and software. To focus on biologically interesting settings, we develop a test for dispersion effects, that is, variance effects not driven solely by mean effects when the trait distribution is non-normal. We apply our approach to body mass index in the subsample of the UK Biobank population with British ancestry (n ∼408,000) and show that our approach can increase the power to detect associated loci. We identify and replicate novel associations with significant variance effects that cannot be explained by the non-normality of body mass index, and we provide suggestive evidence for a connection between leptin levels and body mass index variability.
- The nature of nurture: effects of parental genotypesAugustine Kong, Gudmar Thorleifsson, Michael L Frigge, and 8 more authorsScience, 2018
Sequence variants in the parental genomes that are not transmitted to a child (the proband) are often ignored in genetic studies. Here we show that nontransmitted alleles can affect a child through their impacts on the parents and other relatives, a phenomenon we call "genetic nurture." Using results from a meta-analysis of educational attainment, we find that the polygenic score computed for the nontransmitted alleles of 21,637 probands with at least one parent genotyped has an estimated effect on the educational attainment of the proband that is 29.9% (P = 1.6 × 10⁻¹⁴) of that of the transmitted polygenic score. Genetic nurturing effects of this polygenic score extend to other traits. Paternal and maternal polygenic scores have similar effects on educational attainment, but mothers contribute more than fathers to nutrition- and heath-related traits.


2017
- Selection against variants in the genome associated with educational attainmentAugustine Kong, Michael L Frigge, Gudmar Thorleifsson, and 8 more authorsProceedings of the National Academy of Sciences, 2017
Epidemiological and genetic association studies show that genetics play an important role in the attainment of education. Here, we investigate the effect of this genetic component on the reproductive history of 109,120 Icelanders and the consequent impact on the gene pool over time. We show that an educational attainment polygenic score, POLY_EDU, constructed from results of a recent study is associated with delayed reproduction (P < 10⁻¹⁰⁰) and fewer children overall. The effect is stronger for women and remains highly significant after adjusting for educational attainment. Based on 129,808 Icelanders born between 1910 and 1990, we find that the average POLY_EDU has been declining at a rate of ∼0.010 standard units per decade, which is substantial on an evolutionary timescale. Most importantly, because POLY_EDU only captures a fraction of the overall underlying genetic component the latter could be declining at a rate that is two to three times faster.
2016
- Powerful decomposition of complex traits in a diploid modelJohan Hallin, Kaspar Märtens, Alexander I Young, and 5 more authorsNature Communications, 2016
Explaining trait differences between individuals is a core and challenging aim of life sciences. Here, we introduce a powerful framework for complete decomposition of trait variation into its underlying genetic causes in diploid model organisms. We sequence and systematically pair the recombinant gametes of two intercrossed natural genomes into an array of diploid hybrids with fully assembled and phased genomes, termed Phased Outbred Lines (POLs). We demonstrate the capacity of this approach by partitioning fitness traits of 6,642 Saccharomyces cerevisiae POLs across many environments, achieving near complete trait heritability and precisely estimating additive (73%), dominance (10%), second (7%) and third (1.7%) order epistasis components. We map quantitative trait loci (QTLs) and find nonadditive QTLs to outnumber (3:1) additive loci, dominant contributions to heterosis to outnumber overdominant, and extensive pleiotropy. The POL framework offers the most complete decomposition of diploid traits to date and can be adapted to most model organisms.
- Multiple novel gene-by-environment interactions modify the effect of FTO variants on body mass indexAlexander I Young, Fabian Wauthier, and Peter DonnellyNature communications, 2016
Genetic studies have shown that obesity risk is heritable and that, of the many common variants now associated with body mass index, those in an intron of the fat mass and obesity-associated (FTO) gene have the largest effect. The size of the UK Biobank, and its joint measurement of genetic, anthropometric and lifestyle variables, offers an unprecedented opportunity to assess gene-by-environment interactions in a way that accounts for the dependence between different factors. We jointly examine the evidence for interactions between FTO (rs1421085) and various lifestyle and environmental factors. We report interactions between the FTO variant and each of: frequency of alcohol consumption (P=3.0 × 10⁻⁴); deviations from mean sleep duration (P=8.0 × 10⁻⁴); overall diet (P=5.0 × 10⁻⁶), including added salt (P=1.2 × 10⁻³); and physical activity (P=3.1 × 10⁻⁴).
- Interactions in complex traitsAlexander YoungUniversity of Oxford, 2016
The availability of cheap genotyping technologies has enabled to collection of very large samples with both genetic and phenotypic information, enabling the interrogation of the genetic architecture of complex traits in humans and other organisms. The role of interactions between genetic variants and between genetic variants and environmental factors in complex traits is not well characterised, especially in humans. This is in part due to a lack of theory and methods designed for powerful investigation of interactions in complex traits in large-scale datasets. This thesis develops both theory and methods relating to interactions between genetic variants and between genetic and environmental factors, complemented by empirical analyses aimed at discovering the influence of interactions on complex traits. The effect of genetic variation on trait variation can be decomposed into components reflecting interactions involving different numbers of genetic variants. The first part of this thesis generalises classical theory on the decomposition of the genetic variance into components arising from different types of interaction to finite populations, where the influence of interactions is more easily detected. The theory is applied to determine the proportion of growth variance from pairwise and third and higher order interactions in a yeast cross. The subsequent parts of the thesis are more directly concerned with interactions between genetic variants and environmental factors. It is first demonstrated that multiple lifestyle factors modify the effect of variants in the FTO gene on body mass index (BMI). This motivates the development of the heteroskedastic linear mixed model (HLMM), which exploits changes in variability with genotype to aid discovery of genetic variants involved in interactions. An efficient algorithm for application of the HLMM to large scale datasets is developed and applied to discover genetic variants likely to be involved in interactions on BMI.
2014
- Estimation of epistatic variance components and heritability in founder populations and crossesAlexander I Young, and Richard DurbinGenetics, 2014
Genetic association studies have explained only a small proportion of the estimated heritability of complex traits, leaving the remaining heritability "missing." Genetic interactions have been proposed as an explanation for this, because they lead to overestimates of the heritability and are hard to detect. Whether this explanation is true depends on the proportion of variance attributable to genetic interactions, which is difficult to measure in outbred populations. Founder populations exhibit a greater range of kinship than outbred populations, which helps in fitting the epistatic variance. We extend classic theory to founder populations, giving the covariance between individuals due to epistasis of any order. We recover the classic theory as a limit, and we derive a recently proposed estimator of the narrow sense heritability as a corollary. We extend the variance decomposition to include dominance. We show in simulations that it would be possible to estimate the variance from pairwise interactions with samples of a few thousand from strongly bottlenecked human founder populations, and we provide an analytical approximation of the standard error. Applying these methods to 46 traits measured in a yeast (Saccharomyces cerevisiae) cross, we estimate that pairwise interactions explain 10% of the phenotypic variance on average and that third- and higher-order interactions explain 14% of the phenotypic variance on average. We search for third-order interactions, discovering an interaction that is shared between two traits. Our methods will be relevant to future studies of epistatic variance in founder populations and crosses.
2011
- Quantitative fitness analysis shows that NMD proteins and many other protein complexes suppress or enhance distinct telomere cap defectsStephen Gregory Addinall, Eva-Maria Holstein, Conor Lawless, and 8 more authorsPLoS genetics, 2011
To better understand telomere biology in budding yeast, we have performed systematic suppressor/enhancer analyses on yeast strains containing a point mutation in the essential telomere capping gene CDC13 (cdc13-1) or containing a null mutation in the DNA damage response and telomere capping gene YKU70 (yku70Δ). We performed Quantitative Fitness Analysis (QFA) on thousands of yeast strains containing mutations affecting telomere-capping proteins in combination with a library of systematic gene deletion mutations. To perform QFA, we typically inoculate 384 separate cultures onto solid agar plates and monitor growth of each culture by photography over time. The data are fitted to a logistic population growth model; and growth parameters, such as maximum growth rate and maximum doubling potential, are deduced. QFA reveals that as many as 5% of systematic gene deletions, affecting numerous functional classes, strongly interact with telomere capping defects. We show that, while Cdc13 and Yku70 perform complementary roles in telomere capping, their genetic interaction profiles differ significantly. At least 19 different classes of functionally or physically related proteins can be identified as interacting with cdc13-1, yku70Δ, or both. Each specific genetic interaction informs the roles of individual gene products in telomere biology. One striking example is with genes of the nonsense-mediated RNA decay (NMD) pathway which, when disabled, suppress the conditional cdc13-1 mutation but enhance the null yku70Δ mutation. We show that the suppressing/enhancing role of the NMD pathway at uncapped telomeres is mediated through the levels of Stn1, an essential telomere capping protein, which interacts with Cdc13 and recruitment of telomerase to telomeres. We show that increased Stn1 levels affect growth of cells with telomere capping defects due to cdc13-1 and yku70Δ. QFA is a sensitive, high-throughput method that will also be useful to understand other aspects of microbial cell biology.
2010
- Colonyzer: automated quantification of micro-organism growth characteristics on solid agarConor Lawless, Darren J Wilkinson, Alexander Young, and 2 more authorsBMC bioinformatics, 2010
Background: High-throughput screens comparing growth rates of arrays of distinct micro-organism cultures on solid agar are useful, rapid methods of quantifying genetic interactions. Growth rate is an informative phenotype which can be estimated by measuring cell densities at one or more times after inoculation. Precise estimates can be made by inoculating cultures onto agar and capturing cell density frequently by plate-scanning or photography, especially throughout the exponential growth phase, and summarising growth with a simple dynamic model (e.g. the logistic growth model). In order to parametrize such a model, a robust image analysis tool capable of capturing a wide range of cell densities from plate photographs is required. Results: Colonyzer is a collection of image analysis algorithms for automatic quantification of the size, granularity, colour and location of micro-organism cultures grown on solid agar. Colonyzer is uniquely sensitive to extremely low cell densities photographed after dilute liquid culture inoculation (spotting) due to image segmentation using a mixed Gaussian model for plate-wide thresholding based on pixel intensity. Colonyzer is robust to slight experimental imperfections and corrects for lighting gradients which would otherwise introduce spatial bias to cell density estimates without the need for imaging dummy plates. Colonyzer is general enough to quantify cultures growing in any rectangular array format, either growing after pinning with a dense inoculum or growing with the irregular morphology characteristic of spotted cultures. Colonyzer was developed using the open source packages: Python, RPy and the Python Imaging Library and its source code and documentation are available on SourceForge under GNU General Public License. Colonyzer is adaptable to suit specific requirements: e.g. automatic detection of cultures at irregular locations on streaked plates for robotic picking, or decreasing analysis time by disabling components such as lighting correction or colour measures. Conclusion: Colonyzer can automatically quantify culture growth from large batches of captured images of microbial cultures grown during genome-wide scans over the wide range of cell densities observable after highly dilute liquid spot inoculation, as well as after more concentrated pinning inoculation. Colonyzer is open-source, allowing users to assess it, adapt it to particular research requirements and to contribute to its development.